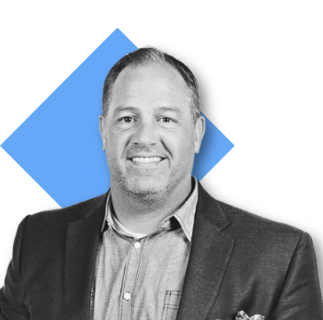

Fırat Mıhcı is the founder and computational linguist behind HumanizeMy.ai, operated by Mihci AI Studios LLC, a U.S.-based research-led AI writing and detection company. He studies how human and machine-generated language differ, why AI detectors produce false positives, and how writing technology can assist people without replacing human judgment. His published research includes analyses of 18,989 scientific abstracts, 510 controlled passages from five language models, 3,300 graded learner essays, and multiple public authorship benchmarks. He translates those findings into product constraints: meaning preservation outranks a more attractive detector score, negative results become stop-rules, and AI may help collect evidence but cannot approve its own conclusions. He publishes methods, findings, code where licensing permits, and limitations through HumanizeMy.ai and ResearchGate. His broader goal is to build practical AI systems whose pricing, performance claims, and customer value can be examined through evidence rather than marketing language.
Company: Mihci AI Studios LLC
We are thrilled to have you join us today, welcome to ValiantCEO Magazine’s exclusive interview! Let’s start off with a little introduction. Tell our readers a bit about yourself and your company.
Fırat Mıhcı: I’m Fırat Mıhcı, founder and computational linguist behind HumanizeMy.ai and MeteGPT, a research-led AI writing and detection platforms operated by Mihci AI Studios LLC in the United States. I built the company around a straightforward conviction: AI products should be judged by evidence, not by the confidence of their marketing language.
HumanizeMy.ai and MeteGPT help people refine AI-assisted drafts while preserving the writer’s intended meaning, voice, and factual responsibility. The product sits on top of an original computational-linguistics research program rather than a collection of surface-level writing tricks. We have studied 18,989 scientific abstracts to track how AI-associated vocabulary enters human-approved writing, compared 510 controlled passages across five language models, examined 3,300 graded learner essays, and tested authorship signals across multiple public benchmarks. We publish our methods, negative results, and limitations through our research hub and ResearchGate so readers can inspect the evidence behind our decisions.
That research discipline also shapes how I run the business. I am a solo founder, so pricing, product quality, research, infrastructure, and customer trust ultimately meet at the same desk. Automation expands capacity, but it cannot approve its own output. A change that improves a detector score but damages meaning does not ship. In the same way, a price that looks attractive on a comparison table but produces unsustainable usage economics is not genuinely customer-friendly, because it eventually forces hidden limits, degraded service, or a price correction.
My goal is to build HumanizeMy.ai and MeteGPT as a serious, durable companies: useful to customers today, transparent about what the science can and cannot establish, and priced in a way that keeps quality and trust aligned as the product grows.
What was the pivotal pricing insight or experiment that most dramatically improved your company’s growth or profitability?
Fırat Mıhcı: The pivotal pricing insight was simple: across HumanizeMy.ai and MeteGPT, we stopped charging customers for a better version of the product and started charging only for the amount of real work they needed to complete.
Many SaaS companies create artificial upgrade pressure by withholding the features that make the product trustworthy. We chose the opposite structure. Every paid plan includes the full humanizer, the enhanced model, and AI-detection checks. A Basic customer does not receive weaker writing or fewer quality safeguards than an Ultra customer. Higher tiers buy capacity, not credibility.
That principle gave us a much cleaner pricing ladder. Basic is $18 monthly and supports 80 requests of up to 1,000 words. Pro is $27 monthly, with up to 150,000 words a month and 1,200 words per request. Ultra is $48 monthly and doubles the Pro allowance to 300,000 words while raising the per-request ceiling to 3,000 words. Annual billing brings the effective monthly prices to $12, $18, and $36 respectively.
The important part is not merely that the numbers rise. Each step corresponds to a different workload. Basic serves light, recurring use. Pro supports sustained professional work. Ultra is designed for power users handling longer documents and twice Pro’s monthly volume. Customers can choose based on the heaviest month they genuinely expect rather than trying to decode which essential feature has been locked behind a higher price.
This also improved the economics of the company. AI products carry more than a token cost: every request can involve infrastructure, retries, evaluation, semantic checks, and capacity held for demand peaks. By scaling price with workload, we can fund those costs without quietly degrading the output or forcing every customer to subsidize the heaviest users. At the same time, the descending unit-cost curve rewards customers who commit to greater volume.
The strategy can be summarized in one line: “Do not make customers upgrade to trust the product; make them upgrade because they need more of a product they already trust.”
That shift turned pricing from a feature maze into a capacity contract. It made the plans easier to understand, the upgrade path more honest, and the cost of maintaining our research and meaning-preservation standards more sustainable.
How do you determine the true value your product or service delivers to customers, and how does that shape your pricing strategy?
Fırat Mıhcı: We define value as a usable, accepted outcome, not as the raw volume of AI computation we sell. A customer does not ultimately want tokens, model calls, or even a particular number of words. They want a draft that is clearer and more natural without losing the meaning, factual responsibility, or personal voice they intended. If the output requires extensive correction, creates a contradiction, or merely produces a more attractive detector score while damaging the text, the nominal usage has little value.
That principle guides both HumanizeMy.ai and MeteGPT. We measure value through three layers.
The first is practical capacity: how much real work can the customer complete in a month, what size documents can they process, and how much friction do the limits create? This is why our plans combine request allowances, monthly capacity, and per-request word limits instead of presenting one vague promise of “more AI.”
The second is avoided rework. A fast result is not valuable if the customer has to reconstruct lost meaning afterward. Our product decisions are constrained by computational-linguistics research covering 18,989 scientific abstracts, 510 controlled passages across five language models, 3,300 graded learner essays, and multiple public authorship benchmarks. That work repeatedly shows that simple surface cues are weaker than people assume. We therefore invest in evaluation and meaning-preservation checks rather than pricing the product as if every generated word were equally successful.
The third layer is trust. The cost of a poor result is not limited to another model call. It can be a damaged argument, an incorrect claim, or false certainty about authorship. Our internal rule is that a more attractive detector score cannot overrule a meaning failure. The price must support the quality gate that enforces that rule.
From there, our strategy is to keep the entry tier accessible, make every increase in capacity economically intelligible, and let higher tiers become less expensive per usable unit without hiding their boundaries. We also avoid pricing around claims the evidence cannot support. A plan creates real value when customers understand what it enables, can use that capacity under normal conditions, and can trust the company to keep delivering the promised quality. Pricing follows that definition rather than attempting to manufacture value through labels.
Can you share one pricing decision (such as packaging, tiering, or a bold price increase) that felt risky at the time but ultimately paid off significantly?
Fırat Mıhcı: The riskiest pricing decision was refusing to use product quality as an upsell.
The conventional SaaS playbook would have been to reserve the enhanced model, detection checks, or stronger quality controls for the most expensive plan. That would have created an easy reason to upgrade, but it would also have meant that customers paying less received a deliberately weaker version of the product. For research-led AI writing products built around meaning preservation, that felt strategically wrong.
We chose a simpler but riskier model across HumanizeMy.ai and MeteGPT: every paid plan includes the complete humanizer, the enhanced model, and AI-detection checks. Customers upgrade only when they need more capacity.
The risk was that we gave up the most obvious feature-gating opportunities. We could not push customers toward Ultra by suggesting that trustworthy output, detection checks, or the complete model required the most expensive subscription. The higher plans had to justify themselves through genuine operational value: more monthly work and longer individual documents.
That decision paid off by making the pricing architecture clearer and more credible. A customer can select a plan by looking at the amount and size of the work they genuinely need to complete. At the same time, usage-based boundaries make infrastructure and evaluation costs more predictable. Heavier users contribute more because they consume more capacity, not because we placed essential quality behind an artificial paywall.
It also created internal discipline. If Ultra cannot earn an upgrade through longer requests and substantially greater monthly capacity, the answer is not to weaken Basic or Pro. The answer is to improve the value of Ultra.
Pricing reveals what a company believes. Our structure says that meaning preservation and core product quality are not luxury features. Customers should pay more for more work, not for permission to trust the result.
“We did not want customers to upgrade for a trustworthy product. We wanted them to upgrade because they needed more of a product they already trusted.”
How do you continuously test and refine pricing without alienating existing customers or damaging brand perception?
Fırat Mıhcı: We refine pricing by testing the assumptions underneath it, not by constantly changing the public number. Frequent price movement can teach customers that the offer is arbitrary, so most of our experimentation happens first in measurement, packaging analysis, and reversible internal models.
We begin with actual behavior by tier: typical document size, monthly word distribution, the number of separate requests required to complete a job, retries, failed or abandoned workflows, support friction, and the infrastructure cost of serving both normal and high-end legitimate use. For an AI product, total words alone are not enough. One long workflow and many short requests may contain the same volume but produce different fixed overhead, latency, and evaluation costs. Looking only at the average customer can also hide a plan that becomes uneconomic at its legitimate upper boundary.
We then compare that behavior with the promise presented on the pricing page. Does each tier solve a recognizably different customer problem? Does the next plan provide a clear capacity or workflow advantage? Does the cost per usable unit decline logically as commitment rises? Can every tier still fund the quality gates behind the output?
Those questions led us to the capacity-led architecture used across HumanizeMy.ai and MeteGPT. The core product is included throughout the paid ladder; what changes is the amount of work and the size of the document a customer can process. The plan boundary therefore corresponds to a real operating need rather than an essential feature we removed to manufacture an upgrade.
When a change is necessary, we protect trust through four rules. Existing commitments are grandfathered when the bargain would otherwise change materially. New packaging is explained in plain language rather than disguised as a promotion. We prefer reversible, observable tests before broad changes. Finally, output meaning, factual care, and customer support never become hidden variables that absorb a cheaper offer.
Brand perception is damaged less by a thoughtful price change than by promising economics the company cannot sustain and later responding with hidden throttles, deteriorating quality, or surprise restrictions. Customers do not need to see every internal cost, but they should understand what each plan is for, where its boundaries are, and why moving upward creates additional value. Our objective is not to maximize the price extracted in a single test. It is to find a structure customers can trust and the company can keep.
For other CEOs who still treat pricing as an afterthought, what’s the single most important mindset shift or first step you would recommend they take?
Fırat Mıhcı: The most important mindset shift is to stop treating pricing as the final layer of marketing and start treating it as product architecture. A price is a compressed promise about who the product is for, what work it can reliably complete, what quality the customer should expect, and whether the company can afford to keep that promise.
The first step is to separate the value every paying customer deserves from the cost driver that genuinely changes as usage grows. At HumanizeMy.ai and MeteGPT, meaning preservation, the complete humanizer, the enhanced model, and detection checks belong in the first category. They define the product, so we do not withhold them to create artificial upgrade pressure. Monthly capacity, request volume, and document size belong in the second category. They increase the real cost of delivery, so they are appropriate reasons for customers to move between plans.
After identifying that dividing line, stress-test the most demanding legitimate workflow allowed by every tier. Calculate variable usage, per-request overhead, retries, evaluation, support, infrastructure held for peaks, payment costs, and the quality controls that cannot be removed without weakening the product. Do not build the economics around an assumption that most customers will never use what you advertised.
Then examine the ladder from the customer’s side. Can someone identify the right plan by describing their workload? Does moving upward provide a visible operating advantage? Is the higher price attached to more value, or merely to the removal of an inconvenience the company created? Strong packaging makes the next step logical without making the entry plan feel intentionally incomplete.
CEOs should also write down what pricing is never allowed to damage. For us, a lower cost or more attractive detector result cannot justify changing the writer’s intended meaning. Our plans must fund the evaluation and research needed to uphold that standard. Every company needs an equivalent non-negotiable: reliability, safety, response time, service depth, or accountable human support.
My advice is: price the accepted outcome and stress-test the promise. If the economics work only when customers underuse the plan, the price is not generous; it is fragile. If customers must upgrade merely to trust the result, the package is not premium; it is incomplete. Good pricing gives people more capacity as they pay more while protecting the quality that made the product worth buying in the first place.