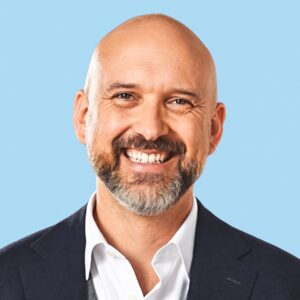
Fırat Mıhcı is the founder and computational linguist behind HumanizeMy.ai, a research-led AI writing and detection platform. He studies how human and machine-generated language differ, why AI detectors produce false positives, and how writing technology can support people without replacing human judgment. His work combines product development with original computational linguistics research, including studies of 2,590 authentic student essays, 18,989 scientific abstracts, cross-model stylistic signatures, second-language writing, and detector reliability. Through HumanizeMy.ai’s open research hub, he publishes methods, findings, and limitations so readers can examine the evidence rather than rely on marketing claims. His broader goal is to build practical AI tools that remain accountable to meaning, authorship, and the lived realities of writers.
Company: HumanizeMy.ai (Mihci AI Studios LLC)
We are thrilled to have you join us today, welcome to ValiantCEO Magazine’s exclusive interview! Let’s start off with a little introduction. Tell our readers a bit about yourself and your company.
Fırat Mıhcı: I’m Fırat Mıhcı, the founder and computational linguist behind HumanizeMy.ai. I built the company without a co-founder around a simple conviction: AI writing technology should be evaluated through evidence, not marketing language. HumanizeMy.ai is a research-led writing and detection platform designed to help people refine AI-assisted drafts while preserving meaning, voice, and human judgment.
The product grew out of work with a corpus of 2,590 authentic essays comprising more than five million words and a broader computational linguistics research program. We have studied AI-associated vocabulary across 18,989 scientific abstracts, stylistic signatures across five language models, the limits of common authorship signals, and the reasons second-language writers can be falsely flagged by detectors. We publish our research, methods, and limitations openly at humanizemy.ai/research, and my papers are also available through ResearchGate.
Building solo has meant turning research discipline into an operating system. I cannot solve every problem through headcount, so I rely on clear measurement, documented processes, selective automation, and strict review gates. AI helps accelerate analysis and execution, but it does not make final judgments about product quality, research methods or conclusions, or customer trust. That combination has allowed HumanizeMy.ai to develop as both a practical product and a serious research presence in AI writing and detection.
What was the biggest advantage and the biggest challenge of building your company as a solo founder, and how did you turn the challenges into strengths?
Fırat Mıhcı: The biggest advantage has been coherence at speed. As the only founder, I can move from a question to a decision without waiting for internal consensus and, more importantly, keep the research, the product, and the public claims aligned to a single standard. In a field where a persuasive demo is routinely mistaken for scientific proof, that alignment is the real differentiator.
HumanizeMy.ai did not start as a SaaS idea. It started with a stranger question: can a mathematically “correct” melody be written, and can tension, surprise, and resolution be measured as structure? That took me from music into pattern analysis and finally to language: does good prose carry a comparable statistical arc? My first hypothesis failed cleanly. Using public benchmarks, the global “surprisal arc” did not separate human from machine text or predict writing quality; it sat at chance. For me, that negative result was not the end of the project. It was the moment it became serious. The signal was elsewhere, in the regularity and self-similarity of machine prose versus human prose. No single metric is a magic verdict, but language leaves enough structural evidence to study honestly. That became HumanizeMy.ai: a tool that refines machine-generated prose while protecting the writer’s meaning, sitting on top of an ongoing computational linguistics research program.
Being solo made that pivot fast. I did not have to convince a committee that a failed hypothesis was still valuable or that the question should change. I could kill a path in the morning, redesign the test by afternoon, and turn the result into a product rule that same week, including the rule that a better detector score is never enough if the output introduces an omission, an addition, or a contradiction. Meaning preservation became a hard gate, not a negotiable feature.
The biggest challenge is the price of that independence. Solo, you do not just make every final call; you carry the full weight of the time, uncertainty, and risk behind it. Research, product, infrastructure, support, and public credibility all draw on one person’s attention, and a wrong decision, or lost time, is not distributed across a founding team.
I turned that into a demand for operating discipline. Important decisions get written down with the evidence, the expected benefit, the failure condition, the smallest reversible test, and the rollback path. Independent benchmarks, user behavior, specialist review, and negative findings are deliberately allowed to contradict me, and product changes must pass the meaning gate before the metric I actually want to move. That gives me the speed of solo leadership without pretending one person’s intuition is enough. The advantage is not just deciding quickly; it is acting quickly while holding a coherent scientific standard.
How did you make high-stakes decisions without a co-founder to debate or validate them with, and what systems or practices helped you avoid costly mistakes?
Fırat Mıhcı: Without a co-founder, no one is automatically in the room to expose a weak assumption, so I have had to build disagreement into the process itself. It runs in four layers.
The most reliable layer is a written decision record. Before a high-stakes change, I state what I expect to improve, the evidence behind that expectation, the outcome that would prove me wrong, the smallest reversible test, and the rollback path. Writing the failure condition before I see the result stops me from quietly redefining success afterward.
The second layer is external evidence that is allowed to say no. I deliberately do not validate the company on my own data; a single author’s corpus has no external validity. The research program runs on independent public benchmarks, and each finding becomes a decision boundary that tells me what not to claim. One study across three public benchmarks showed that a document’s global surprisal pattern does not reliably establish authorship or quality, which killed an overconfident detection idea. A controlled study of 510 passages from five models found that style separates the vendor family, OpenAI versus Anthropic, with 96% reliability (AUC 0.96), while the exact model can be identified only 50% of the time, against a 20% chance baseline. That is a direct warning against turning a broad stylistic signal into a forensic claim. A study of 18,989 arXiv abstracts showed that the “AI vocabulary” detectors lean on is a moving, contaminating target, not a timeless fingerprint. These are not just papers; each one narrows what the product is allowed to promise.
The third layer is a quality gate that outranks the metric I am chasing. I once tested approaches that produced excellent automated-detection numbers and looked ready to ship, until a separate semantic review found omissions, additions, or contradictions in some outputs. Because I had already decided that meaning preservation outranks the detector score, I stopped them. Neither my enthusiasm nor the good numbers got to overrule the gate.
The fourth layer attacks the solo blind spot directly, and I am still building it: a human-behavior simulation, a local development and rethinking of the “Light Society” one-billion-agent model, grounded in World Values Survey data across a large, demographically varied respondent set. The point is to give a solo founder a synthetic room of many perspectives before spending heavily. It is early; so far, I have validated that it reproduces the published social-behavior signatures. I treat it as one input that can surface objections I had not considered, never as an oracle. Real user behavior and independent benchmarks still decide.
So the pattern is: widen the perspectives, reduce the decision to a falsifiable and reversible test, and let a predeclared standard say no. A co-founder might have supplied instant debate; I have had to design that debate so it is documented and repeatable, instead of depending on whether two people happen to challenge the right assumption on the right evening. I still carry the final call. I have simply made sure that one mind does not get to generate the idea, represent the audience, judge the evidence, and approve the result unopposed.
Can you share one key system, hire, or operational decision that allowed you to scale beyond what most people assume a solo founder can achieve?
Fırat Mıhcı: The single decision that let me operate beyond what one person is usually expected to cover was to build a research-to-product operating loop in which automation increases capacity but is never allowed to approve its own work.
In practice, I treat almost everything the company does, including research analysis, the product pipeline, content, and deployment, as a sequence of stages, and I sort each stage into one of two bins. Repeatable, judgment-light work is automated aggressively, including with LLM-driven agents: data collection, feature extraction, reproducible analysis runs, and build-and-deploy with an automatic rollback path. Judgment-heavy work stays explicit and manual: deciding whether to trust a result, checking that meaning survived a rewrite, editorial sign-off, and choosing what to claim in public. Automation multiplies throughput; a human gate at the end of every pipeline protects quality. Software is a force multiplier, not a substitute for judgment.
The effect is that one person can sustain things that normally imply a team. On the research side, the same loop has produced a series of public, independently benchmarked studies with permanent DOIs, the kind of output that usually needs a small lab, because the tooling is reproducible with a single command and only the interpretation is manual. On the product side, a change moves from hypothesis to a live, verified deployment with a rollback path without me hand-carrying every step. Research and product feed each other through the same loop: a finding becomes a product boundary, and a user problem becomes the next research question.
The deeper payoff is that the loop attacks the largest hidden cost of solo founding: re-deriving the same judgment every week. Because standards, gates, and negative results are written down once, new work simply has to meet them. I am not rebuilding the reasoning from scratch each time. A failed experiment still earns its keep by narrowing the search space, and a documented limitation becomes a guardrail the automation has to respect.
It is not costless, and I learned the boundary the hard way. There was a period when I let automated throughput run ahead of the gates, and some of the output did not justify its own existence. The fix was not less automation; it was stronger gates and slower expansion. That correction is exactly why the system works now: capacity scales through automation, but nothing ships until the part that genuinely requires a human has cleared it.
How did you manage the emotional and mental load of carrying the full weight of the company alone, especially during periods of uncertainty or rapid growth?
Fırat Mıhcı: I do not manage the emotional load of solo leadership by trying to convince myself that everything will work. I manage it by trusting the scientific process, trusting the discipline of the work, and knowing that I am willing to work hard enough to find out when I am wrong. My confidence does not come from believing every hypothesis I have. It comes from believing that a careful process can turn uncertainty into evidence.
That became personal very early in the company’s story. The question that eventually led to HumanizeMy.ai began in music: could a mathematically correct melody be written, and could tension, surprise, and resolution be measured? When I transferred that idea into language, I expected prose to reveal a similarly clear global surprisal arc. The evidence did not support the elegant answer I had imagined. After investing time in the hypothesis, seeing a controlled negative result was disappointing. But I preserved the finding, followed the adjacent questions, and found something more useful in the regularity and self-similarity patterns of human and machine prose. The original idea did not have to be “right” for the work to have value. The process led me to a better question and, eventually, a company.
That experience still shapes how I respond to pressure. When you are alone, a failed experiment can easily feel like a judgment on you rather than information about the experiment. There is no co-founder beside you to say, “The hypothesis failed; you did not.” I had to learn to create that separation myself. A failed quality gate is the system protecting the customer. A negative result narrows the search space. A difficult week is not evidence that the mission is wrong.
A particularly demanding period came when a major search update exposed that our publishing pace had moved faster than the differentiation of some content. The emotionally tempting response was to publish more, blame an external change, or defend work because I had already invested in it. Instead, I paused expansion, audited the pattern, removed material that did not justify its existence, and strengthened the editorial gates. Recovery was slower than a quick-fix story would have been, but the company became more honest and more aligned with its research-led identity.
I also limit how many problems I allow to become existential at the same time. Some problems are operational, some are waiting for data, and some genuinely threaten trust. Naming the category helps me respond proportionately. Written decisions and preserved negative results also stop me from repeatedly carrying the same uncertainty.
What sustains me is a combination of effort and method. I know how much time I give the work, but effort alone is not enough; it must be disciplined by evidence. Science gives me permission to change my mind without treating that change as weakness. Process gives me a way to keep moving when confidence fluctuates. The emotional goal is not to become detached. It is to remain accountable without allowing fear, pride, or fatigue to rewrite what the evidence says.
For other founders considering going solo or already building without a co-founder, what’s the most important piece of advice you’d give them about scaling successfully on their own?
Fırat Mıhcı: Do not romanticize being solo. Build an institution around the fact that one person carries the final responsibility.
The speed is real. A solo founder can go from an unusual question to a working experiment without spending weeks winning agreement. HumanizeMy.ai came out of exactly that freedom, through a chain of hypotheses that mostly failed in their original form. If every change of direction had needed a committee, the company probably would not exist. But the cost is just as real: you will invest an enormous amount of time, and the financial, technical, and reputational risk will not be split across a founding team. Independence is only sustainable if you design systems so that not every decision depends on your energy that day.
Four things have mattered most.
Write an operating constitution: decide what you will not trade for momentum. For us, meaning preservation outranks a more impressive detector score, and a public claim needs a dated method, real evidence, and an honest limitation. Those rules have killed promising experiments and slowed attractive marketing ideas, and they have saved me from mistakes far more expensive than moving slowly.
Manufacture disagreement on purpose. Solo should not mean single-minded. I use user behavior, independent benchmarks, specialist review, written pre-mortems, and increasingly a human-behavior simulation with diverse agent profiles to attack my own assumptions. The one condition that makes it real is that the feedback must be allowed to change the plan. Feedback that cannot say no is reassurance, not governance.
Document repeated judgment, not just repeated tasks. Founders are told to automate email and deployment, but the bigger leak is re-deriving the same decision every week. If you have weighed the same kind of risk three times, write the criteria. If every release needs factual, semantic, and rollback checks, make them gates. If an experiment fails, keep the reason. A negative result is an asset when it stops you buying the same lesson twice.
Protect your ability to continue. I will not pretend solo building is a productivity trick that removes sacrifice. The point is not to avoid effort; it is to make the effort accumulate. A documented standard should make the next decision easier, a research finding should become a product boundary, and a complaint should become a testable hypothesis. If each hard week leaves reusable knowledge behind, the company gets stronger without the founder having to personally remember and repeat everything.
The deepest lesson is that the real solo advantage is clarity, not control. I can move fast because I know what the company is protecting: the writer’s meaning, scientific honesty, and user trust. But clarity has to be paired with mechanisms that protect you from your own certainty. You do not need a co-founder to build a serious company, but you do need opposition, evidence, documented standards, outside expertise, and stop-rules. Stay solo in accountability if it suits you; never stay isolated in perspective. Scale the quality of your decisions before you scale the volume of your work.